 By theo
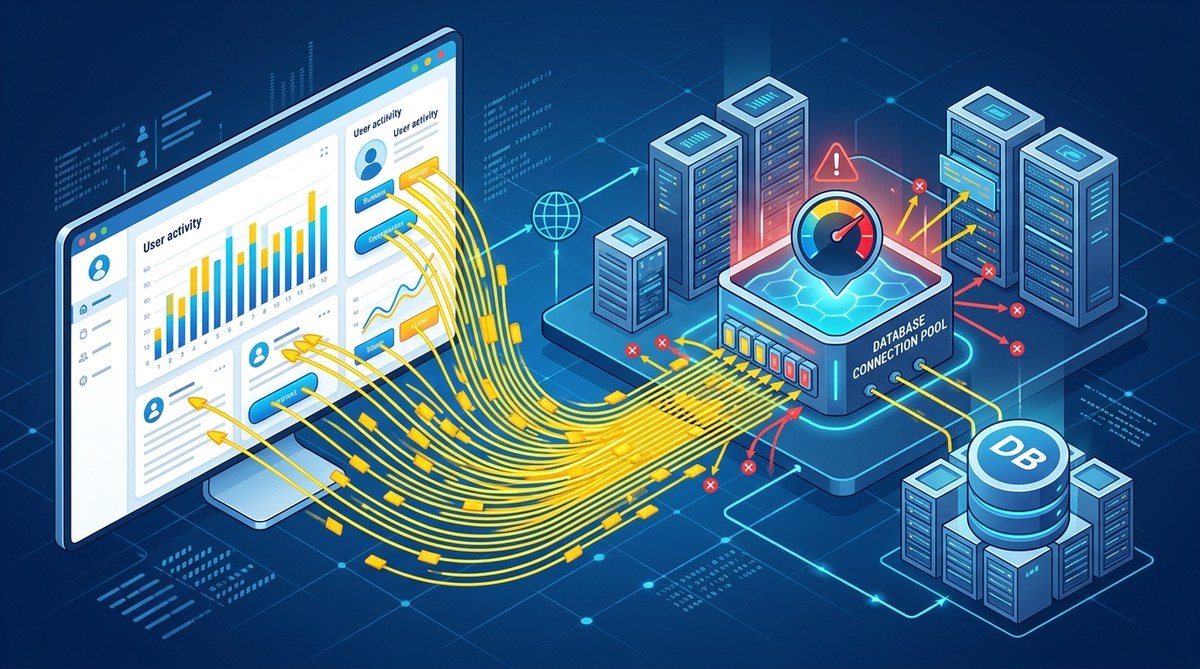
You are staring at a production alert. Your database connection pool is exhausted. Requests are failing. Your first instinct is to blame the backend, maybe a slow query or a misconfigured pool size. You tweak the connection limits, restart the service, and hope it holds. But the error comes back an hour later. The real cause is probably not where you are looking. It is in the browser.
Database connection pool exhaustion is rarely a pure backend problem. Frontend behavior such as aggressive retry loops, unclosed HTTP connections, and excessive parallel requests can drain a pool faster than any slow query. By tracing the full request lifecycle from browser to database, you can identify patterns like connection leaks and request amplification. Fixing these on the frontend often resolves the backend error without changing a single line of server code.
The Hidden Link Between the Browser and Your Database
When a user clicks a button, their browser sends an HTTP request. That request travels through your load balancer, hits your application server, and eventually opens a connection to your database. Every connection uses a slot in your pool. If the pool is full, new requests wait or fail.
Most backend developers treat the pool as a server-side resource. You set a max of 50 or 100 connections and assume that is enough. But the frontend controls how many requests are sent, how fast they arrive, and how long connections stay open. If the frontend behaves poorly, it can flood the pool.
Consider a single page that makes 12 API calls on load. If 100 users refresh simultaneously, that is 1,200 requests hitting your servers. If each request opens a database connection and holds it for 500 milliseconds, you need at least 600 concurrent connections just to handle that burst. Most default pool sizes are smaller.
How Frontend Patterns Drain Your Pool
Let us look at the specific patterns that cause database connection pool exhaustion from the frontend.
1. Uncontrolled Retry Loops
A user sees a spinning loader. Their patience runs out. They click the refresh button. Their browser, or your JavaScript, retries the failed request. If you have written a retry loop that fires every 200 milliseconds, you are generating a wave of connections.
The problem compounds when multiple users do this at the same time. A brief backend slowdown can trigger a retry storm. Each retry opens a new database connection while the previous one may still be active. The pool fills up and stays full.
2. Connection Leaks Through Keep-Alive
HTTP keep-alive allows a single TCP connection to send multiple requests. This is efficient until something goes wrong. If your frontend code fails to properly close or reuse connections, each request can open a new TCP socket. Those sockets wait for a timeout before the server releases the database connection.
A common scenario is a WebSocket or Server-Sent Events (SSE) stream that fails to reconnect cleanly. Each failed attempt leaves a stale connection in the pool. Over time, these orphaned slots accumulate.
3. Excessive Parallel Requests
Modern single-page applications often fetch data in parallel. A dashboard might request 10 different endpoints at once. This is fine for a few users. But when traffic spikes, the database sees a sudden wall of connections.
The worst case is an infinite scroll or polling endpoint. If your frontend polls every 200 milliseconds and the response takes 300 milliseconds, you have overlapping requests. Each one claims a connection slot.
4. Slow Client Consumption
Your backend sends a large dataset. The database holds the connection open until all data is transferred. If the frontend reads the response slowly, or if the client has a poor network, the connection stays open longer than expected.
This is especially common with streaming responses or large JSON payloads. The database connection pool fills up not because of high throughput, but because connections live too long.
A Practical Process to Diagnose the Root Cause
When you see pool exhaustion, do not start by increasing the pool size. Follow this numbered process to find the real source.
-
Check your request logs for patterns. Look at the distribution of incoming requests over time. Do you see spikes that correlate with user actions like page loads or button clicks? Filter by endpoint and look for repeated calls from the same IP or session.
-
Inspect the timing of database connections. Use your database monitoring tools to see when connections are opened and closed. Compare that to the request timestamps. Look for connections that stay open longer than the average response time.
-
Review frontend error handling. Read the code that runs after a failed API call. Does it retry immediately? Does it have exponential backoff? Does it ever stop retrying? A missing retry limit is a common culprit.
-
Simulate a slow backend. In a staging environment, add an artificial delay to an endpoint. Watch how the frontend behaves. Does it queue up multiple requests? Does it open new connections before the old ones finish?
-
Monitor connection pool metrics during a traffic test. Load test your application with realistic user behavior, including page refreshes and error scenarios. Watch the pool usage in real time.
Common Frontend Mistakes vs. Backend Fixes
The table below compares what you might be tempted to fix on the backend versus what you should fix on the frontend.
| Mistake on Frontend | Typical Backend Fix | Better Frontend Fix |
|---|---|---|
| Infinite retry loop | Increase pool size | Add exponential backoff and a max retry count |
| Parallel requests on page load | Add more database replicas | Batch requests or use a single aggregator endpoint |
| No connection reuse | Tune keep-alive timeouts | Implement connection pooling in the HTTP client |
| Polling too frequently | Reduce pool timeout | Increase the polling interval or switch to WebSockets |
| Large payloads slow to consume | Increase connection limits | Paginate results or stream data with backpressure |
The Retry Storm in Detail
A retry storm is one of the fastest ways to exhaust a pool. Here is how it works.
Your frontend calls an API. The API needs a database connection. All slots are busy. The request fails with a 503 or a timeout. Your frontend catches the error and retries immediately. It does this every 100 milliseconds.
Now imagine 50 users are hitting the same endpoint. That is 500 requests per second. Each request tries to grab a connection, fails, and releases it. But the act of trying uses a slot for a brief moment. The pool is in constant churn. No legitimate request can get through.
The fix is simple. Use exponential backoff. Start with a 1-second delay, then 2 seconds, then 4 seconds. Cap the number of retries at 3 or 5. This gives the backend time to recover.
Expert advice: Always set a maximum retry count. An infinite retry loop is a denial of service attack against your own database. Treat it like a bug, not a feature.
How to Fix the Frontend Without Touching the Backend
You do not need to rewrite your server code to solve pool exhaustion. These changes live entirely in the browser.
- Add a request queue. Instead of firing 10 parallel requests, queue them and send them sequentially. This reduces the peak connection load.
- Use a single connection for multiple calls. If you are using HTTP/2 or a WebSocket, reuse the same TCP connection. This prevents each request from opening a new database slot.
- Implement circuit breakers. If your frontend detects a high failure rate, stop sending requests for a period. This gives the pool time to drain.
- Close idle connections. Make sure your HTTP client does not leave connections open after a timeout. Set explicit timeouts on both the client and server side.
- Cache aggressively. If the data does not change often, cache it on the frontend or in a CDN. Fewer requests mean fewer database connections.
For more on improving your debugging approach, see our guide on common JavaScript debugging tricks every developer should know. It covers techniques that help you spot these patterns earlier.
When the Frontend Is Not the Problem
Sometimes the pool exhaustion is genuinely a backend issue. A slow query can hold a connection for seconds. A missing index can cause full table scans. But even then, the frontend amplifies the problem.
If a single query takes 2 seconds and you have 50 users, that is 100 seconds of connection time. With a pool of 50, you will see errors. The fix is to optimize the query. But you should also check if the frontend is sending that query unnecessarily.
Ask yourself: Does the frontend need to call this endpoint on every page load? Can the result be cached? Can you reduce the frequency of the call? These questions often reveal a frontend optimization that is easier than a database migration.
Tools to Trace the Full Request Path
To confirm that the frontend is the source, you need visibility across the stack.
- Application Performance Monitoring (APM). Tools like Datadog or New Relic show you the full trace from HTTP request to database query. Look for requests that overlap or repeat.
- Browser developer tools. Check the Network tab in Chrome or Firefox. Look for duplicate requests, rapid retries, or requests that do not complete.
- Database connection logs. Most databases log when a connection is opened and closed. Parse these logs to see the pattern of activity.
- Load testing with realistic user behavior. Use tools like k6 or Locust to simulate users who refresh pages and trigger errors. Compare the connection pool usage to your production data.
If you are seeing errors that only appear in production, read our article on why your production errors don’t show up in local development. It explains why the frontend behaves differently under load.
A Checklist for Your Next Incident
When the next pool exhaustion alert fires, run through this bulleted list before touching the server config.
- Check the frontend error logs for retry loops.
- Look at the request rate per user session.
- Verify that HTTP connections are reused correctly.
- Confirm that polling intervals are not too short.
- Test if caching can reduce the request volume.
- Review the frontend code for missing timeout values.
- Simulate a slow network to see how the frontend reacts.
The One Change That Stops Most Pool Exhaustion
If you can only make one change, add a retry policy with exponential backoff and a maximum of 3 attempts. This single fix prevents retry storms, which are the most common cause of frontend-driven pool exhaustion.
Pair it with a circuit breaker that stops all requests for 10 seconds after a 50% failure rate. This gives your pool time to recover. Your users will see a brief delay instead of a broken page.
For a deeper look at related issues, check out our guide on troubleshooting API response errors in web applications. It covers how to distinguish between client-side and server-side failures.
Where to Go Next
Database connection pool exhaustion is a symptom of a larger problem. The frontend and backend are not separate systems. They are two ends of the same pipe. When one end misbehaves, the other end breaks.
Start treating your frontend as a first-class citizen in your database performance strategy. Monitor it. Test it under load. And when you see a pool exhaustion error, look at the browser first. You might find that the fix is a few lines of JavaScript, not a server restart.
If you want to improve your overall debugging approach, our guide on mastering debugging strategies for frontend JavaScript errors is a good next step. It will help you catch these patterns before they reach production.
The next time your database pool runs dry, remember that the browser is often the one turning the faucet. Turn it off there, and the pool will fill back up on its own.